On applying ethics to the LLMs and coding assistants situation

It often frustrates technologists that there isn’t an algorithm for deciding ethical behavior. You can’t follow a checklist or a set of rules to decide whether something’s ethical or not (or you can, but people might still disagree with you). That said there are professional codes of practice that apply to our work, and in the field of computing one of the clearest is the ACM Code of Ethics and Professional Conduct jointly developed by the ACM, IFIP, and IEEE. Here’s how I interpret its position on LLMs with respect to a few points: I’m interested to hear how you evaluate the ethical nature of LLM adoption with respect to the other parts of the Code.

A computing professional should…

1.1 Contribute to society and to human well-being, acknowledging that all people are stakeholders in computing.

It’s not clear that the current crop of leading frontier companies are uniformly doing this. For example, Dario Amodei’s statements about AI leading to a white-collar bloodbath and being a general labor substitute show an inclination to oversell his products to managers, not to engage with the wider impact on society. Meanwhile, Altman takes the view that the dream jobs of the last five years will be replaced by new careers, a less apocalyptic and more actionable view.

1.2 Avoid harm.
In this document, “harm” means negative consequences, especially when those consequences are significant and unjust. Examples of harm include unjustified physical or mental injury, unjustified destruction or disclosure of information, and unjustified damage to property, reputation, and the environment. This list is not exhaustive.

The clearest story here is that in the world of cybersecurity, the AI tools have (it seems) vastly increased the attacking capabilities without similar effects on defensive capabilities.

Another clear one is the bugginess people associate with vibe-coded software. Yes, it genuinely exists, and in the famous examples of deleting production databases the products have caused “unjustified destruction of information”. Of course, humans do make mistakes sometimes, and I’ve worked at pretty big companies where someone has accidentally destroyed production data, but it feels like a foreseeable outcome of using a coding assistant that it might automate such destruction. This is consistent with the situation where companies elevate the prominence of their AI-generated summaries or advice and put “please check this, it might contain a mistake” in small print; it feels more like paying lip service to avoiding damage than actually taking steps to do it.

A place where I’ll disagree with others is the old energy/water/data centres saw. On the one hand, it’s clear that these harms are being overstated for political gain. On another hand, it’s clear that the hardware and data center companies are pursuing more efficient and sustainable innovations; for example, zero liquid discharge cooling systems, and reduced cooling-energy consumption systems.

It could be argued, though one would need to carefully check the various organisations’ actual actions to confirm this, that the hyperscalers are pursuing “growth at any cost” and therefore failing to “promote environmental sustainability both locally and globally”. However, the remedy might be to ensure they put a sustainability plan in place and potentially even impose a moratorium pending that plan, it shouldn’t be to completely withdraw from participating in the development and exploitation of LLM technology, or impose a worldwide ban on others doing it. That throws the baby out with the bathwater, as it were, saying that society is permitted none of the benefits of the new technology.

1.5 Respect the work required to produce new ideas, inventions, creative works, and computing artifacts.

It’s evident through the legal settlements that there are disagreements over whether frontier LLM-training organisations respect the creative effort that goes into producing new works (it’s also a feature of a settlement that no wrongdoing is implied).

The problem of applying copyright in the digital domain, where creative works have no physical presence and are readily distributable, hasn’t really been resolved, and so there are some weird situations right now. For example, it’s entirely valid to buy a book so that you can scan it into a computer, because there’s a common idea of the First Sale Doctrine that says once you own something, it’s yours to do with as you want.

On the other hand, were you to buy an ebook and transform it into a different computerised format, you might not only violate the license agreement with the ebook supplier, but face criminal action for circumventing a copy protection mechanism.

In short, the situation for creative control and protection of digital works is “nuts”, society doesn’t evidently demonstrate clear agreement on what is or isn’t acceptable, but these new processes and the way they transform their input data are a clear change to the parameters of the conversation that’s desperately needed.

Posted in AI, philosophy after a fashion, Responsibility | Leave a comment

On taking developments in software engineering personally

Much of the feedback on my recent article on Reasons to Dislike AI Coding featured a dismissal of a collection of common themes in arguments against AI coding, without any thesis. That post was indeed my way of collecting thoughts, and connecting them to existing articles where I’d already addressed some of the concerns: I don’t think I dismissed the thematic arguments so much as referred to my own, or other, arguments. Here we are, a month later, and I’m ready for the synthesis.

For a lot of software engineers—myself included—the arrival of AI coding assistants represented an existential threat of sorts. Here’s a thing that I’m good at, have made a reputation for being good at and had what I hoped was the first half of a career out of being good at. Now here’s a tool that does it not as well as I do it, that everyone’s going nuts over as the future of the craft of doing the thing. It’s easy to take that personally and to get angry and upset about the change in technology. I know that, because I’ve done it before.

Instance One: Unix

The thing that tipped me from programming as a hobby to programming as a potential career path was using NeXTSTEP at university. I’d already encountered FreeBSD and Linux, and “knew” that Unix-like systems were the technologically superior choice for workstation operating environments. However, even I had to accept that they weren’t exactly pleasant to configure. While the hacking community recommended tinkering with Linux to learn more about how computers and networking work, I was ready to acknowledge that 80% of what you learned through tinkering with Linux was how to tinker with Linux (if you’ve edited sendmail.cf or XF86Config, or gone through the kernel’s make config without access to menuconfig, you know what I mean).

NeXTSTEP demonstrated that you could have the power of UNIX with the elegance of a consistent, well-designed user interface. Admittedly that assessment ignored a lot of rough edges, but it felt clear that NeXTSTEP was the best of the best. Mac OS X was evidence that this technology was ready for primetime, even if (to me) it had various borderline-acceptable compromises to make it work with the legacy Apple landscape.

So imagine my surprise, nay consternation, at going to work in my early 20s as a NeXT/general-Unix-like sysadmin, then programmer, to find out that the people I worked with were far from jealous that I was the person working on the best computers. Some of them not only voluntarily worked on Windows NT, but even claimed to like it!? Imagine my upset to hear that a NeXT-based solution wasn’t automatically chosen just for the pedestrian reason that other people had accidentally bought suboptimal workstations!

Much of this came from my initial cultural introduction to the sysadmin world, which was through a collection of university Unix admins who very much subscribed to the BOFH mindset and communicated in phrases from the ESR jargon file. Indeed, their secret, back-channel mailing list was even called CBOFH…compleat bastard operators from hell.

I never consciously trained myself out of this one; the whole non-Microsoft world and bits of Microsoft vindicated the Unix choice at about the same rate that my opinions mellowed, so I became able to avoid having that argument around the time that it went away.

Instance Two: Smalltalk and Objective-C

Having been a NeXT person, I naturally fell into the classical object-oriented, message-passing, extreme late binding world of software design. And got, if I may say so, rather good at it (my M.Sc. dissertation was an interactive live coding environment that used LLVM as a JIT to dynamically execute ObjC code). I did quite well out of understanding problems from the perspective of networks of interacting agents that send each other messages; making expressive, concise, efficient designs using advanced runtime techniques; and helping others to do the same. Mostly in Objective-C, the language of the NeXT, and of the iPhone and iPad Gold Rushes; also Smalltalk, Python, Java, and Ruby.

Imagine then, my confusion, and the threat to my sense of psychological safety, when the entire field started moving in the opposite direction; towards compiler appeasement and specifying all the bindings in advance. TypeScript was OK because it cleaned up some of JavaScript’s gnarly edges, but Go and Rust seemed like unnecessary distractions when investing in analysis tooling for existing languages gave the benefits of continuing to use legacy code and high-fidelity design techniques while also gaining the benefits of fixing common bugs in memory management and variable misuse.

But eventually, the type supremacists came for ObjC, and we got Swift, a programming language that promised to deliver efficient and correct code across a range of application domains and that eventually got there. This one felt like a shot that landed too close to home, and along with a period of career burnout and break, personal life upheaval and depression, I did what the no-AI people are doing today: I opted out. I spent a year not working at all, then did what someone described as “entering witness protection” and went off to have a career outside my comfort zone: in local companies that had no technology relationship with the field I’d left or the field that had left me. I tried to prove that my software engineering knowledge was domain-agnostic and translational, and in doing so left behind my communities, relationships, and other support structures.

It took me four years to even engage with the Apple-developer world at all, and eight years to get comfortable with the idea of doing my stuff in Swift, the tool that I felt had pulled the rug out from under my career back in 2014. This was a long, and unhealthy, reaction to a technical change.

Instance Three: AI-Augmented Coding Assistants

Like many other people, I initially reacted negatively to the rise of LLMs. Firstly, because of the cavalier approach some of the frontier companies took to copyright; as a Free Software person, I’m already part of a plot to nullify proprietorial stances in software, thank you very much. Then, because the early models made bad software. And then, because an LLM can’t understand software engineering, it can only generate code.

But this time, I reacted differently. Instead of withdrawing from software engineering, I asked how I use my knowledge and skills in this world. What’s the way I contribute, and feel empowered and safe, with this new development? Further, how many other people are going through this difficult shift, and how can I contribute to their empowerment and safety? Chiron Codex continues to be an attempt to answer that question, nearly a year later.

Posted in advancement of the self, AI | 1 Comment

Episode 67: The Scrum Guide

This episode investigates a philosophical shift in the way people tried to understand software towards the end of the 20th century, and then discusses one of the most impactful, if not widely adored, documents of the post-shift era. The episode is supported by members of the Chiron Codex Patreon (use this gift link for your first month free), so please do join the community or hit the Ko-Fi button to make a one-off donation. If you enjoy the episode, share it with at least one friend, colleague, or stranger.

Links

Leave a comment

Announcing Axminster: visual software design

Axminster, my diagrammatic software design tool with LLM support, is now available for sale! Check out the product website for more info.

Posted in software-engineering, tool-support | Leave a comment

Episode 66: No Silver Bullet

This episode discusses both Fred Brooks’ classic paper on the likelihood of 10x improvements in software engineering productivity, and his reflections on its interpretation 9 years after publication. The episode is supported by members of the Chiron Codex Patreon (use this gift link for your first month free), so please do join the community or hit the Ko-Fi button to make a one-off donation. If you enjoy the episode, share it with at least one friend, colleague, or stranger.

Note that with this episode I have moved from supplying a text transcript in the post body, to a downloadable .vtt file. If you’re looking for the transcript, please download the linked file.

Links

Leave a comment

Episode 65: The Frog and the Octopus

This episode considers a method-free approach to software engineering methodology, and a request to include the context of a software project in the attempts to sell techniques and processes. The episode is supported by members of the Chiron Codex Patreon (use this gift link for your first month free), so please do join the community or hit the Ko-Fi button to make a one-off donation. If you enjoy the episode, share it with at least one friend, colleague, or stranger.

Links

Transcript

Hello and welcome to episode 65 of the Structure and
Interpretation of Computer Programmers podcast. I’m Graham
Lee. The episode is sponsored by you, the software
engineering community. If you enjoy this podcast, please
share the link with your friends and colleagues. You can give
feedback on this episode by commenting on the post at
sicpers.info slash podcast, that’s s-i-c-p-e-r-s dot info
slash podcast, or by sending me an email, grahamlee at
acm.org.

There are many problems with software engineering
methodologies. Methodology, by the way, is the study of
method. So we’re in the realm of software engineering
metaphysics, thinking not so much about how the sausage gets
made, but about how people design, build, deploy and service
sausage-making machines. So a problem with software
engineering methodology is a problem of working out how to
define or apply a software engineering process, how to
instantiate the idea of software engineering in a specific
context.

And it’s identifying that context and tailoring a method to
the context that is one of the biggest problems. It’s
actually difficult to get people to tell you when a
particular approach to software engineering does or doesn’t
apply.

Oh, you can get someone to tell you, but rarely is that
someone one of the creators, the methodologists themselves.
You won’t find any scoping or context information in the
documentation for the methodology or framework. As an
experiment, look at “What is Scrum?” on scrum.org, or read
the Scrum guide at scrumguides.org, and now try to come up
with an answer to this question. When do the creators of
Scrum think it’s an appropriate tool to apply? Or this
question: in what contexts do the creators of Scrum think
that you should reach for an alternative approach?

Of course, you can search the internet for individual answers
to the question from people who have tried it and found that
it doesn’t work for them, or from advocates who definitely
think you should be using it for whatever it is that you’re
trying to do. That’s far from systematic, it’s far
from…methodological.

People who found that it doesn’t apply might have the wrong
context, or they might have the wrong skills, or might have
understood the process incorrectly. Scrum, particularly, is a
baseline process and a process improvement framework, and
most places I’ve seen that “do Scrum”, with my podcast scare
quote fingers, don’t have any experience at process maturity
or improvement. So they either do the baseline process
forever and complain that it’s stultifying, or they tweak it
into something that doesn’t work for them, and then complain
that it doesn’t work for them.

The result of this lack of contextual or scoping guidance is
you get these bags of apparently associated practices that
promise to control your software development work, and no
particular reason to choose one over another. Nobody explains
why Scrum has all the Scrum practices, and why XP has all the
XP practices. Further, they don’t explain why Scrum doesn’t
have the XP practices, and vice versa. Is there actually a
problem with having both a sprint retrospective and a
sustainable pace? What do the methodologists know about how
these practices combine that they don’t tell us?

The world would look very different if we had a context-aware
approach to selecting software methodologies. If you could
fill out a real or metaphorical checklist, and it would tell
you, “okay, so you’ve got a department of 25 engineers at a
growth stage fintech, working on a service for one big-ticket
customer. You use these practices.” Or it tells you, “with
your three PhD students, fixed term, fixed budget, creating
biophysical simulation software, you should do these things.”

There was meaningful discussion on this topic back in the
1990s and 2000s. Diane Kelly observed that the definition of
computer science as a distinct mathematical discipline
independent of the business of making software, –
incidentally, that’s a topic I’ve covered multiple times in
past episodes – that definition of computer science led to
computing experts favouring generic, domain-independent
techniques, methods, and paradigms. This, in turn, led to a
rise of one-size-fits-all, or domain-independent management
paradigms, which meant, to use her words, “a reorganisation
along the lines of all software is treated the same, all
developers are the same.”

In practice, scientists writing software for research aren’t
the same as Java coders toiling in feature factories. So
software engineering methodology, in fact, developed blinkers
in which people either worked the way methodologists
expected, or they were doing something different, which
placed them beyond the methodologist’s comprehension and
therefore beyond any help. A “chasm” opened up between the
domains where methodology worked and those where it didn’t
apply, which Kelly hoped that we could bridge by considering
domain-relevant or domain-specific methodologies. That, of
course, didn’t happen.

So now we come to the document at the core of this week’s
episode. In 2011’s “The Frog and the Octopus”, Philippe
Kruchten wants to abandon the “methodologies” (plural noun
that really means named software development processes), and
replace them with “methodology” (uncountable noun that means
the study of software development method). His goal is
nothing short of a unified model of software that applies to
any domain. To help us to get there, he separates software
engineering into the things that everybody does, which he
calls the frog, and the things that lend context specificity,
which he calls the octopus. And then he has a third category
that doesn’t have an animal name. We’ll get to that later.

This is the advert break. It starts now.

Your development team is slowed down, your customers are
frustrated, and your support team is constantly banging down
the door. Nobody can find the information they need, and they
struggle to talk to each other to work it out. Relationships
on the team have soured, with developers, QA, and ops
all-taking, and us-versus-them position. Your backlog grows
faster than the team delivers features. Retrospectives
involve more finger-pointing than decision-making. This
sounds like a case for Software Craftsmanship’s consulting
detective. That’s me. Discover your team’s friction points,
and create realistic action plans for improvement.
Restructure your delivery pipeline to bridge the quality gap,
automate improvements, and reduce rework. Then, take
ownership of the documentation, and curate a knowledge hub
that keeps information flowing throughout your organization,
empowering engineers, executives, partners, and customers
alike. Find out more, and book a free initial assessment at
sicpers.info.agency. That’s s-i-c-p-e-r-s dot i-n-f-o slash
agency. Together with me, Software Craftsmanship’s consulting
detective will crack the case.

That was the advert break. It’s over now.

The frog is the central concept of a “project”; an attempt to
achieve some goal by producing some output with some
resources and some people within some amount of time. In
fact, I’ve almost listed all of the nine categories in the
frog part of the model in that one sentence. To be more
explicit, we’re talking about:

  • the intent: what somebody aims to achieve
  • the product: what they expect to make in an effort to
    achieve their intent
  • work: what people do to turn the intent into a product
  • the people: who does the work
  • time: the evolution of the other attributes
  • quality: desirable parameters of the other attributes
    and the values of those parameters
  • risk: uncertainty related to the other attributes
  • value and cost: the resources unlocked by achieving
    the intent or creating the product, and the resources
    required to get the people to do the work that means the
    intent is achieved or the product is created; and finally,
  • project, the metaphorical boundary that encapsulates all
    of the above.

So are these attributes of the frog truly universal? I’d say
that this is one of those questions where you learn something
about the philosophy of the person who answers the question
from the way in which they answer it. You might say that a
hobby open source endeavour doesn’t really have any risk
because it’s just a hobby. It doesn’t have any cost because
it’s just a hobby. And it doesn’t have a project because
there’s no timescale, no stakeholders and no stated
deliverables.

Or you might say that those things are present. The main risk
is that the hobbyist finds a different hobby. The cost is the
opportunity cost of the time they put into their hobby. And
the various projects are anything from “I’m going to put in a
couple of hours on optimising spline reticulation this
evening”, to “I want to have these three features before I
release a v2, hopefully by the end of this year.”

Kruchten takes the latter position. All of those things are
present. And the fact that the software is part of a hobby
open source project is important context that modifies the
importance of some of the “frog” attributes of the software
endeavour.

In fact, there’s really nothing about software in the frog at
all, despite the number of times that Kruchten says
“software” in this section of the paper. Really, this is a
model of a generic knowledge-work project, which only doesn’t
translate to tangible production because there are no
facilities, materials, inventory or capital. But software
projects do have those things. What gives? Again, philosophy.
They’re not important enough, to Kruchten at least, to
materialise in the paper. They’re kind of hidden in the idea
of costs.

So that was the frog. Then there’s the octopus. This is all
of the context in which the project occurs, which gives it
its unique flavour. If, like me, you’re confused about the
frog imagery, you’re on safer ground with the octopus because
there are eight categories, or arms I suppose, of context.

Well, sort of. In fact, there are two components to the
octopus, one of which has five arms and the other eight. So
maybe it’s an octopus riding a starfish? I’m just going to go
and rewatch The Little Mermaid because it’s possible that
that’s actually a named character.

Anyway, Kruchten divides
the octopus into variations at the project level, of which there are eight, and at the organisation
level, of which there are five. The eight project level variables are:

  1. size. He says the overall size of the system under
    development, but it isn’t clear if that means the size of the
    product or the size of the intent. Maybe it’s both. Maybe
    some organisations set out to create large software because
    they think it’s better in some way, or they set out to create
    small software for the same reason.
  2. Architectural stability.
  3. Financial model.
  4. Team distribution.
  5. Rate of change, by which he means the volatility of the
    business environment and the associated uncertainty, not the
    rate at which people change the software.
  6. The age of the system, through which we infer
    that the product can vary between new features in an existing system, to novel product, to ground up
    rewrite.
  7. Criticality, i.e. how safety critical is the system. And;
  8. Governance.

I’m largely happy to go along with all of this, except that I
think it’s a bit arbitrary to separate criticality and
governance. Criticality is really about the magnitude of
risks to external stakeholders, and governance is the way
that you vary your work to address or to avoid or to ignore
those risks. You could take a completely freewheeling
approach to avionics software, thus fail at any compliance
goals, which would expose some huge risks, not least of which
being you probably wouldn’t be allowed to sell your product.
You could take a safety critical approach to developing a
casual mobile game, which would expose some other huge risks.
I suppose you do need eight arms for an octopus though, so
both are listed.

That then brings us on to the five arms of the organizational level factors:

  1. Business domain.
  2. Number of instances (of the deployed system).
  3. Organizational maturity.
  4. Level of innovation. And;
  5. Culture, which is further divided into social culture,
    that’s the norms and values of the society in which the
    workers are embedded. Corporate culture, which is the way the
    organization thinks about things. And ethical culture, the
    way the workers and managers think about responsibility to
    other stakeholders.

So the big idea is that the way you do software depends on
all of these things in both the frog and the octopus. But the
most software methods or methodologies focus on the frog and
ignore the octopus. They pretend they have a
one-size-fits-all process that anyone who wants people to
make software can apply. The frog gives you a model you can
use to critique a project. “How do you measure the quality of
the product?” “What risks are associated with the people on
this project?” And so on. And the octopus gives you a model
you can use to critique the applicability of a practice,
process or tool to your specific context. “I have 10,000
people on three continents. Should I do a daily scrum?” “Does
the idea of minimal viable product make sense for my two-year
fixed-term fixed-budget research project?” And so on.

These methodological ideas reach peak maturity in an approach
that Kruchten worked on with Ivar Jacobsen, Bertrand Meyer
and others called SEMAT, S-E-M-A-T, Software Engineering
Methods and Tools. The SEMAT kernel recommends not thinking
about a methodology as a package of practices but about
software development as a system in which the main
interacting components are what the SEMAT methodologists call
the “alphas”: opportunity, stakeholders, requirements,
software system, team, work and way of working.

These seven alphas approximately map onto parts of the frog
and the rest of the process is about identifying your
particular challenges and opportunities, i.e. mapping your
octopus, and then thinking critically about how a given
intervention, adopting a technique, abandoning a technique,
selecting a tool and so on, would change the different alphas.

We have still to address the third unnamed part of the frog
and octopus model, that is the tacit-slash-explicit
dimension. How much the knowledge and ways of working in an
organisation are documented and follow the documentation, and
how much they are unstated shared cultural assumptions that
everyone “knows”.

The idea of tacit knowledge is a crucial part of the theory
of Communities of Practice. Communities of Practice is a
theory largely worked out by Etienne Wenger to explain how
people who have some shared interest in performing a
practice, whether it’s work related, a hobby practice, an
educational requirement, a form of religious worship or
something else, come together to collectively enthuse about
the practice and in doing so develop a shared understanding
of the practice and even shared rules about how to perform
the practice that don’t necessarily correlate with any formal
instructions, documentation or reporting structure in the
practice’s setting.

In the frog and octopus model, this forms another contextual
component. You need your people to have a shared model of the
intent, the product, the people and the work. How much of
that that do you infuse culturally, and how much do you share
in documentation, and how much is out of your hands because
people make it up in their communities of practice? What kind
of documentation should you use? Dashboard, wall of cards,
task tracker, wiki, bulletin board, chat forum, formal
processes, checklists, employee handbooks, something else.

Tacit/explicit knowledge is the least explored of the
dimensions, mostly because if you’re trying to sell a
technique or a product, it’s better if it’s tangible, and
saying “our product enhances the tacit knowledge of your
workers so they do things in ways that are out of your
control” doesn’t sell very well to managers. Perhaps it could
be one of the most interesting and impactful dimensions
though, especially in this age, of tools that build software
based on your explicit description of what you want,
completely ignorant of all tacit context.

A methodology that explicitly surfaces all ambiguity in
product requirements, ways of working, interpersonal
relationships, software design, quality expectations, and the
rest of the frog, right at the point that you try to feed all
of that information into a large language model, could be the
defining feature of post-2023 software engineering. Or it
could be a hugely onerous, wasteful, and bloated process, and
you’re better off leaning into the ambiguities and just
having your people take their coffee breaks together so that
whoever types a prompt into the model already has a good idea
what the customer was thinking. That second approach has
generally been considered a good idea for the last three
decades or more. Maybe it’s still a good idea today.

As ever, share your thoughts on this episode in the comments
on the sicpers.info website, that’s S-I-C-P-E-R-S.info, or
email grahamlee at acm.org. Recommend the podcast to your
friends, find more info at the Patreon page linked in the
show notes, and the reading list at se100.chironcodex.com,
and let’s talk soon.

3 Comments

Inter-process communication in a sandboxed Mac app

Axminster—my graphical software design tool for the AI coding age—is still in beta, and it’s already been through three different technologies for inter-process communication (IPC). What gives?

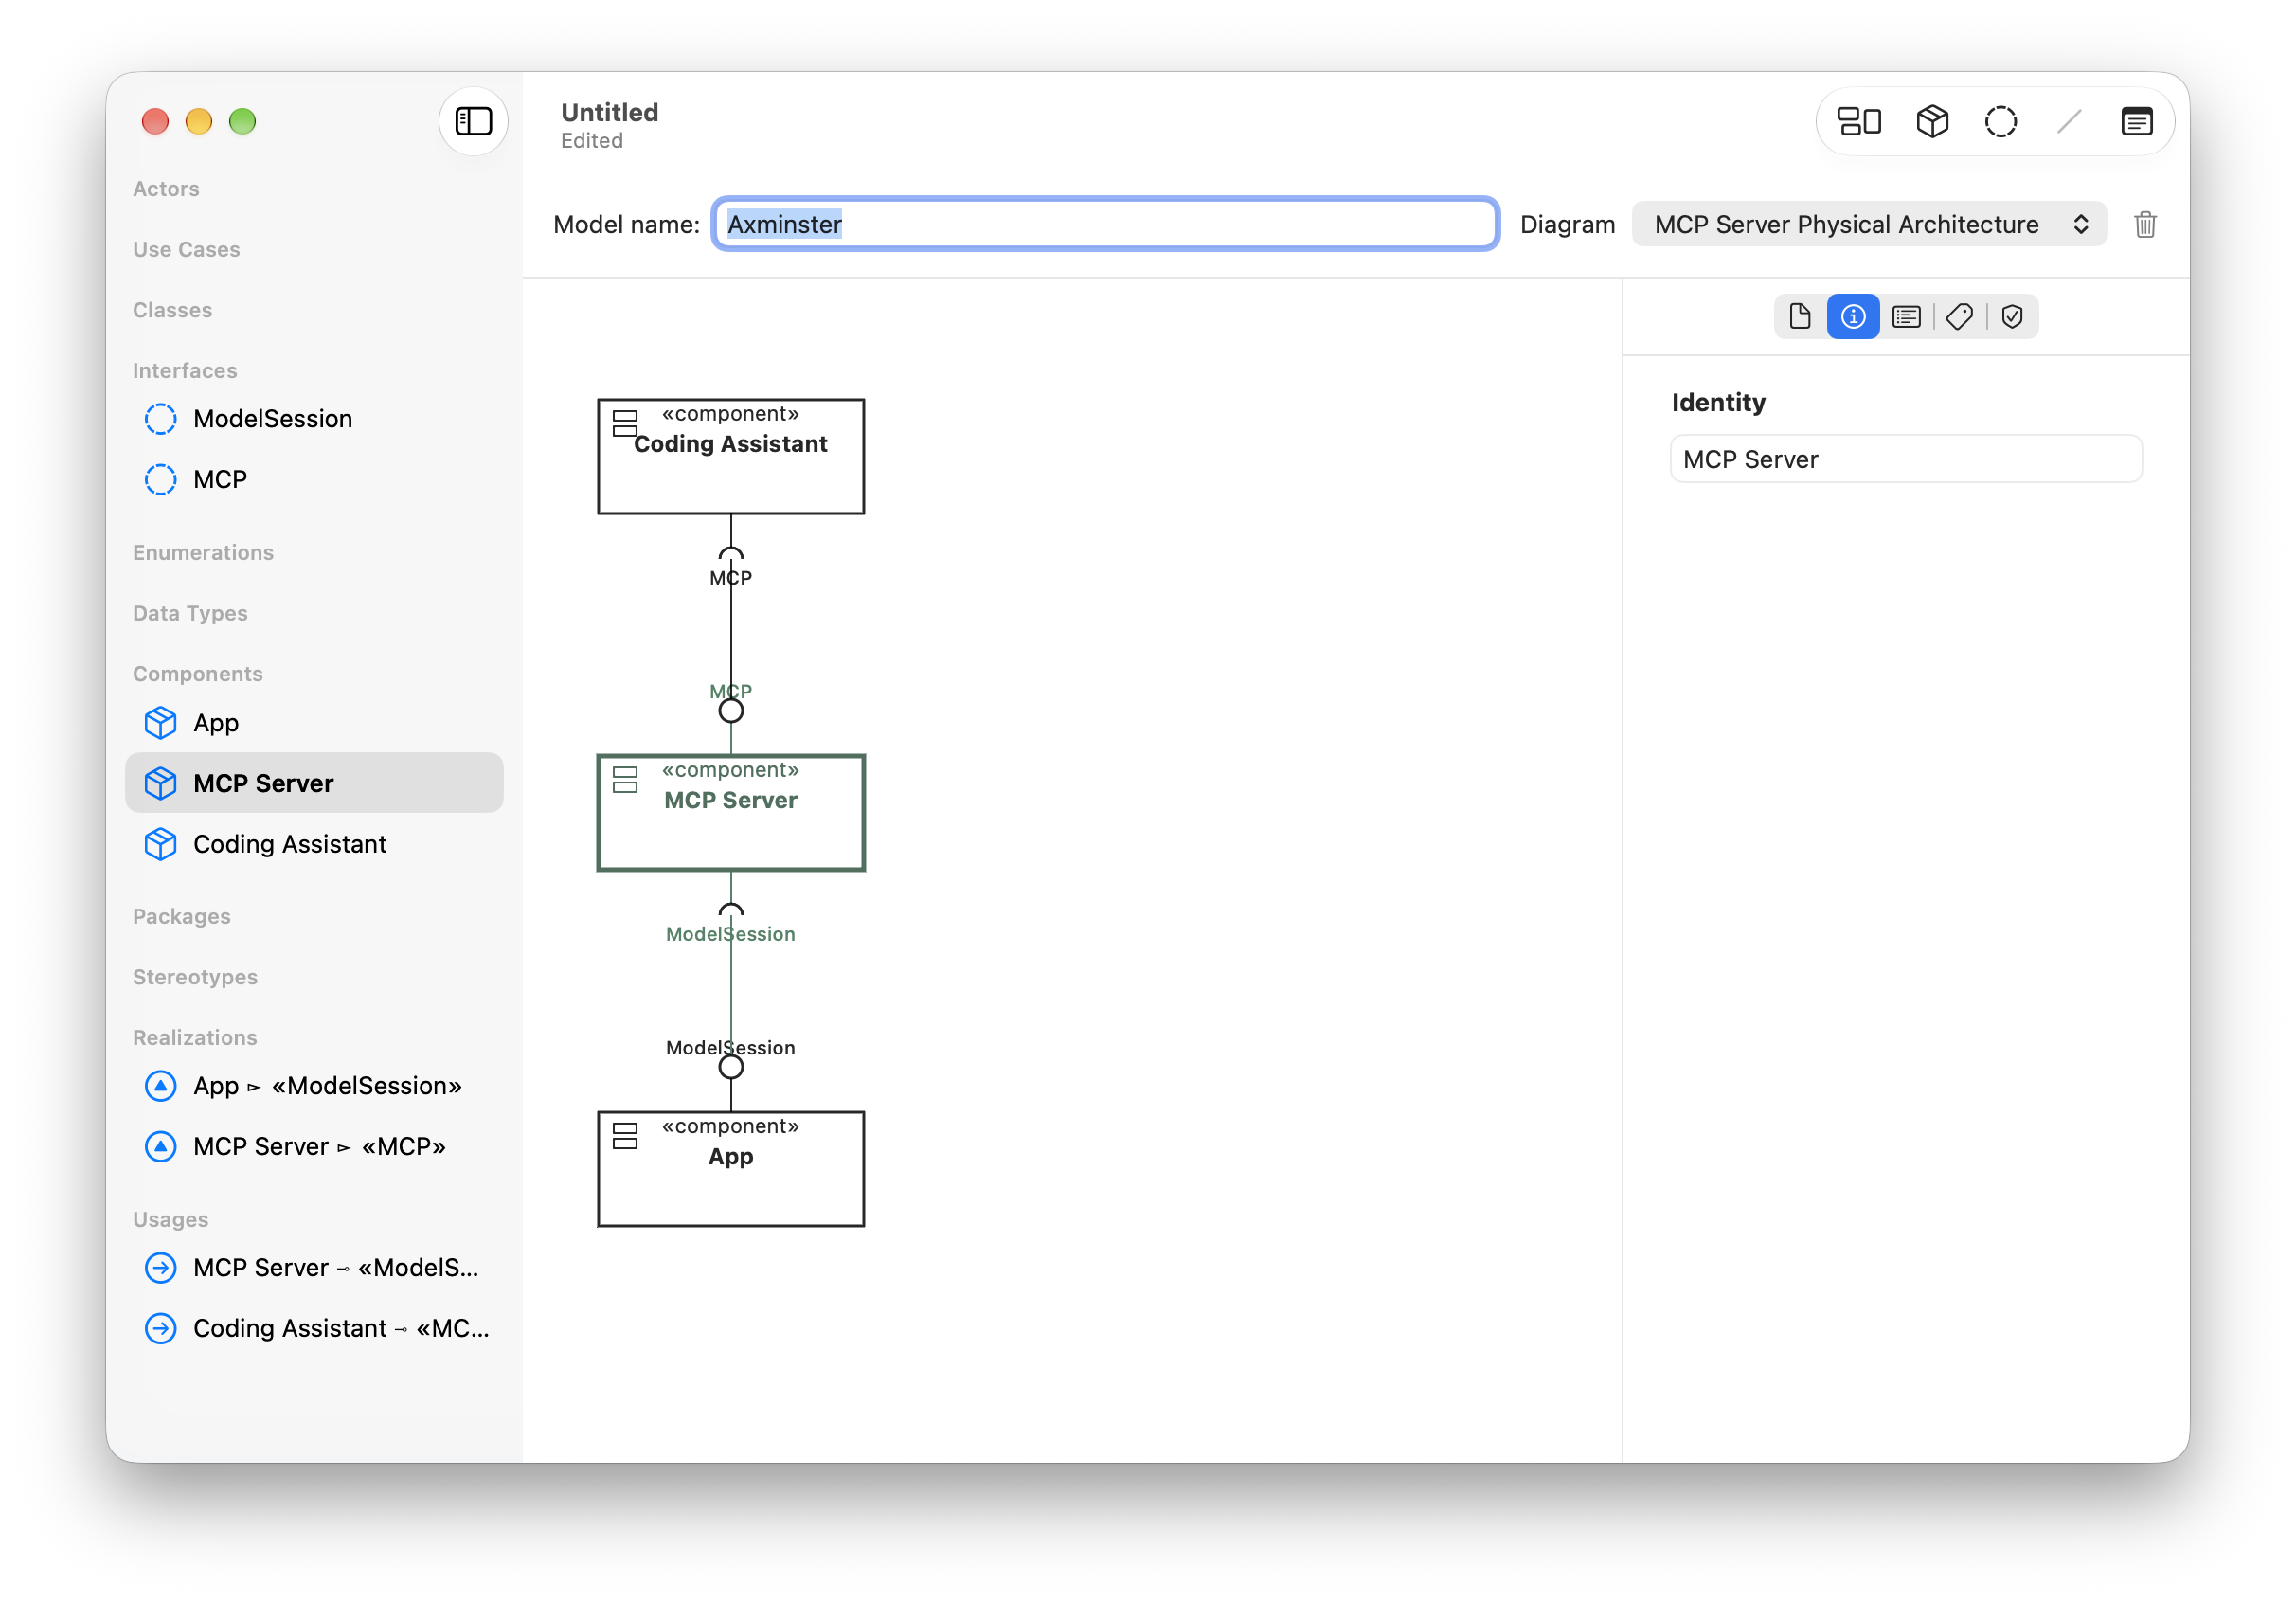
The reason the app needs IPC at all is to support the Model Context Protocol (MCP), which is how your LLM coding assistant reads and manipulates your diagrammatic model. I’ll start by showing you how it works now, which is that there are two components in Axminster—the app itself, and a small MCP helper tool that forwards requests to the app over a UNIX domain socket.

My first attempt avoided the helper process, and relied on an HTTP server inside the Axminster app to serve MCP. This was the easiest to get going from the App Sandbox perspective, as it just means adding the incoming network connections entitlement.

However, it’s pretty bad from a security perspective. Any process running locally on the Mac can connect to the server, so a different app potentially controlled by a different user can view and change someone’s models. This was always a beta-only approach used to get something out quickly that testers could validate, with the risks clearly explained in the documentation.

The second approach switched to a helper tool that outwardly uses the stdio MCP protocol; it needs to be a helper tool because the process lifecycle is controlled by the MCP client (the coding assistant), not the Axminster app. That means that the app and the helper need their own IPC mechanism so that MCP requests sent to the tool get relayed to the app.

Putting the app and the helper into the same app group gives them a shared container, and access to a few different IPC mechanisms. I initially chose to use an XPC service; as the App Groups doc says, I should be OK as long as I prefix the XPC service’s name with the group identifier.

And yes, dear reader, I was OK, unfortunately everybody else wasn’t OK. In testing, this worked well; the helper (deployed in Axminster.app/Contents/Helpers/axminster-mcp) connected to the app, launching it if necessary, each end evaluated the other end’s identity to ensure it talked to the correct process, and then MCP traffic flowed. However, the first TestFlight feedback I got after making this change was that the MCP server no longer connects.

I’m not entirely sure why, but the XPC connection worked when I launched the app in Xcode, but not when I launched it from the Dock. Because nobody else has my Xcode project, it didn’t work for them. I didn’t get to the bottom of that, because I switched the IPC to its final state—a UNIX domain socket in the App Group’s shared container. The two peers still get each other’s identity to ensure they’re talking to the correct executable (this time by getting the PID from the socket), so otherwise nothing is changed.

Posted in cocoa | Leave a comment

Reasons to dislike AI coding

Code as Art

I covered this before in Art or tool? If you think of software as artistic output then generated software isn’t real because it doesn’t have the creative ineffability that’s a sign of true art.

There’s no argument against this one except that the people who want software typically aren’t paying for artworks, they’re paying for outcomes. And the outcomes of using a given artefact are the same regardless of how the artefact is made.

That also means there’s no argument for this one, unless you accept as axiomatic the ideas that things that can be considered art should only be made by people, and that using this particular set of tools is too big a separation between the person and the work when no other historical set of tools was too big a separation between the person and the work.

AI as Employment Thief

I covered this one before too, in On working machines. If you think of typing in code as the thing you get paid for, and the employers now have access to a machine that can do the typing, then the machine “stole your jobs”.

Except that the job was never to type code, it was to deliver valuable software. People who can still do that can still get paid by organisations that need that to be done. And, as I said in the linked post, demand only increases as application becomes more efficient.

Humans as Meat Proxies

If you think that software creation is an interpersonal endeavour, then taking task descriptions generated by software and turning them into prompts that the software uses to generate more software is a dehumanising experience.

This has been the trajectory of society for centuries. Here’s a quote from the Fragment on Machines:

…once adopted into the production process of capital, the means of labour passes through different metamorphoses, whose culmination is the machine, or rather, an automatic system of machinery (system of machinery: the automatic one is merely its most complete, most adequate form, and alone transforms machinery into a system), set in motion by an automaton, a moving power that moves itself; this automaton consisting of numerous mechanical and intellectual organs, so that the workers themselves are cast merely as its conscious linkages. […]

The accumulation of knowledge and of skill, of the general productive forces of the social brain, is thus absorbed into capital, as opposed to labour, and hence appears as an attribute of capital, and more specifically of fixed capital, in so far as it enters into the production process as a means of production proper.

This passage, written by Karl Marx in about 1857-1858, shows that both mechanical and intellectual work was always intended to be replaced by machinery (in predicting the alienation of intellectual work, Marx probably relied on his knowledge of contemporary mathematician Charles Babbage). In this situation it isn’t the technology that takes the job, it’s the mode of production. And given that programming is intellectual work, the means of production is literally our heads, we ought to be able to seize those.

Software Engineering as Rules

Motivated by Bertrand Meyer’s AI for Smarties, if you believe that software engineering is the careful application of the mysterious knowledge of software engineers, encapsulated in rules like the SOLID principles, “prefer composition over inheritance”, “use you’re type’s good“, the Law of Demeter and so on, then AI can’t possibly write software because it doesn’t apply those rules, it just generates text that happens to compile.

Never mind that much of the history of computing involves people taking an empiricist approach to software: copying it from Stack Overflow and tweaking it until it works; writing it out from a listing in Numerical Recipes or Sinclair User and tweaking it until it works; writing macros to automate the copying phase, and so on.

AI Companies as Bad Actors

If you believe that the big AI companies is run by people who don’t have humanity’s best interests at heart (further reading: all the Karl Marx writings I didn’t already quote above), then AI coding is bad because it supports those companies. As long as you don’t allow for the creation of other companies, the use of non-corporate models like academic or community models, and so on.

Posted in AI | 3 Comments

AI adoption, engineering process, and documentation consultancy

I’m available as a consultant on the things I do: helping developers understand AI; interpreting software engineering knowledge in depth; and writing precise documentation that’s easy to understand.

Head over to the agency page to discover how to hire Software Craftsmanship’s consulting detective.

Posted in AI, documentation | Leave a comment

Episode 64: Using Pattern Languages for Object-Oriented Programs

This episode looks at the origin of design patterns in software, their development, and the limited exposure many software engineers have to the idea. The episode is supported by members of the Chiron Codex Patreon (use this gift link for your first month free), so please do join the community or hit the Ko-Fi button to make a one-off donation. If you enjoy the episode, share it with at least one friend, colleague, or stranger.

Links

Transcript

Hello, and welcome to episode 64 of the Structure and Interpretation of Computer Programmers podcast. I’m Graham Lee. This episode is sponsored by you, the software engineering community. If you enjoy this podcast, please share the link with your friends and colleagues. You can give feedback on this episode by commenting on the post at sicpers.info slash podcast, that’s s-i-c-p-e-r-s dot info slash podcast, or by sending me an email, grahamlee at acm.org.

Most programmers who have encountered pattern languages in software engineering have read one of two books, either Design Patterns by the Gang of Four, that’s Gamma, Helm, Johnson and Vlissides, or Head First Design Patterns by a gang of four authors, Freeman, Robson, Bates and Sierra. Both books probably sold in about equal quantities, and both represent a tiny window into the world of pattern languages and software.

The Gang of Four book propelled the idea of a pattern language of software design into the mainstream. It was instantly popular when introduced at eCOOP 1993, that’s the European Conference on Object-Oriented Programming, and it remains in print to this day. I have the 32nd printing from 2005, and a book still available in hardcover 21 years later. Martin Fowler called it “the best book ever written on object-oriented design, possibly of any style of design”.

If the Gang of Four book brought design patterns to the mainstream, Head First Design Patterns explained the idea to a mainstream that struggled with the dense style of the first book. However, people came away, whether they had read both, one or neither of those books, with the idea that the catalogue of patterns in the books is all there is to learn, that if you identify state machines in your system and implement them using the state pattern, identify component interfaces in your system and implement them using the mediator or facade patterns, and identify one-off objects in your system and write a blog post decrying the singleton pattern, you’re doing design patterns.

Worst of all, they learned that design patterns are about system implementation, that they tell you something about how to design classes and interfaces in your code, that the appropriate person to apply design patterns is a programmer. In fact, this distortion of the value of pattern languages is so egregious, and yet so successful, that in 1999, the Gang of Four were subjected to a tongue-in-cheek show trial at the OOPSLA, that’s Object-Oriented Programming Systems Languages and Applications Conference. Their charges include having promoted a cult of personality and brought about the establishment of a cottage industry of consultants, trainers and sundry acolytes to interpret their abstruse musings. They are said to have, by making it possible to design object-oriented programs in C++, have inhibited the rightful growth of competing object-oriented languages such as Smalltalk, CLOS, that’s the common Lisp object system, and Java, and by distilling hard-won design expertise into patterns, have encouraged novices to act like experts.

We need to burn everything down and start again. I’ll start with computers, though, and specifically go back to the beginning of applying pattern languages to object-oriented software systems. I already wrote a whole series of posts over on my blog about the genesis and evolution of the model-view controller pattern. Links in show notes. And MVC is almost certainly the first pattern explicitly shared for the purpose of guiding software design.

But the place where people realised this approach to software design, describing a common problem and its solution, packaged in such a way that someone else who has the problem can learn how to apply the solution alongside the problems that they just invented for themselves by doing so, could be a general approach to software design. And one that works well in the object-oriented paradigm was OOPSLA87, and specifically a technical report by Kent Beck of Apple Computer and Ward Cunningham of Tektronix called Using Pattern Languages for Object-Oriented Programs.

Pattern languages weren’t invented by Beck or Cunningham, or even by any of the MVC people, Adele Goldberg, Trygve Reenskaug, and the other Smalltalkers. The idea comes from the world of built architecture, most influentially from Christopher Alexander. He says, despite being a professional architect, that we, humanity, don’t really know how to design buildings, spaces, and structures. He proposes that the best people to design and build a structure, like a building or a town, are the people who live, work, or play in that structure, because they’re the people who know what they need, and they’re the people who will have to adapt to the realities of the structure, assuming it actually gets built.

A pattern language in construction or architecture is a guided tour of the knowledge of that field, expressed in a form that lays out a problem people have, a solution to that problem, how it compares with alternative solutions, and other problems you might encounter by applying that solution, and hence, other patterns you might want to consider. For example, Small Public Square is a pattern that applies to a town. They give people a place to meet, and if town squares are too big, then they feel empty. The existence of a Small Public Square might generate a Promenade, but then you have to think about Pedestrian Density. Both Promenade and Pedestrian Density are other design patterns. This language then forms a shared vocabulary between lay designers and architects, so that the people who live in a town can say, we want a Beer Hall on our Small Public Square, and the architects know what a Beer Hall is, and can ask follow-on questions, say, the number of Alcoves, and the Ceiling Height Variety. Ideally, the pattern language is acyclic, so that at some point you can actually finish designing and get on with construction.

Inventing our own realistic example, hundreds of years ago, many buildings had roofs that were made of thatched straw or rush, and opened fires in the middle of the floor. This worked okay, because the thatch let the smoke eventually dissipate, and in fact the warm, smoky air kept a lot of vermin out of the thatched roof. Over a long period, from the 12th to the 18th centuries, people started building chimneys instead. These are ventilation shafts incorporated into the building structure, that exhaust the hot, smoky gases from the fire to the outside directly. Chimneys have benefits. The air inside the building is cleaner, for example. And drawbacks. A lot of the heat from a fire escapes through the chimney. They also motivate related concerns. For example, you have to get the shape of the flue correct, to avoid blowing air from the outside down the chimney, and distributing your fire throughout the building. And you have to build the chimney from non-combustible materials, for reasons that seem obvious now, but apparently weren’t in the 15th and 16th centuries. These requirements both weren’t understood by builders who saw other buildings use chimneys and copied them in their own short-lived designs.

So an architect might create a pattern called Chimney that solves the problem of smoky air in a building and relates to other patterns like ventilation and fire safety. Then when someone’s talking about heating their office or house, the architect can propose a Chimney, though these days they might want to suggest Heat Pump or HVAC instead.

A pattern language is an evolving argot because our understanding changes and the things we’re trying to do change. Christopher Alexander’s 1977 work on a pattern language for built architecture doesn’t include anything about cell towers, working in coffee shops, or the effects of influencers making TikToks on pedestrian density, to cite a few examples.

This is the advert break.
It starts now.

Your development team is slowed down, your customers are frustrated, and your support team is constantly banging down the door. Nobody can find the information they need, and they struggle to talk to each other to work it out. Relationships on the team have soured, with developers, QA and ops all taking an us-versus-them position. Your backlog grows faster than the team delivers features. Retrospectives involve more finger-pointing than decision-making. This sounds like a case for Software Craftsmanship’s consulting detective. That’s me. Discover your team’s friction points and create realistic action plans for improvement. Restructure your delivery pipeline to bridge the quality gap, automate improvements, and reduce rework. Then, take ownership of the documentation, and curate a knowledge hub that keeps information flowing throughout your organization, empowering engineers, executives, partners, and customers alike. Find out more, and book a free initial assessment at sicpers.info/agency. That’s S-I-C-P-E-R-S dot I-N-F-O slash agency. Together with me, Software Craftsmanship’s consulting detective, we’ll crack the case.

That was the advert break.
It’s over now.

Beck and Cunningham propose applying this idea to software. People who will use the software are the best people to design the software because they know what they need and will have to adapt to the realities of the software, assuming it gets built. So a pattern language of software provides a catalogue of known problems, their solutions, and links with related patterns that a software user and software builder can use to understand the design together.

The new hotness in the 1980s was graphical user interfaces, with Smalltalk being the first environment to both make GUIs accessible and adopts the principle that software is designed and made by people who use it. So the patterns that Beck and Cunningham propose start with interaction patterns for designing software’s user interface. They list five design patterns for windows in Smalltalk. Window Per Task, Few Panes Per Window, Standard Panes, Short Menus, and Nouns and Verbs. Even without the detailed pattern descriptions, it’s clear what motivates these patterns and how to apply them.

Beck and Cunningham explain how these patterns then lead on to implementation patterns, describing one called Collect Low-Level Protocol. Kent Beck eventually published some of these implementation patterns as the book Smalltalk Best Practice Patterns, which I would argue, while remaining conscious that more people listen to Martin Fowler than to me, is truly one of the greatest books in object-oriented design. Even if you never touch Smalltalk and never have touched Smalltalk, read this book, and you’ll learn something about designing software and refactoring, back from before it had that name, refactoring your software towards a design.

Indeed, it was Smalltalk Best Practice Patterns that served as the inspiration for my upcoming book, Patterns in AI Augmented Software Development. Beck described, writing the patterns on index cards that he riffled through when stuck for ideas on the code he worked on. I found things that I, or my colleagues, did repeatedly when trying to get coding assistants to correctly complete a task, and I wrote those on index cards so I could try them again the next time. Over time, and with more conversations with people who use AI tools, I firmed up my understanding of some of the patterns, decided that others weren’t in as wide use as I would want to see to confirm that they represent reusable patterns, and rejected some, because even though people were doing them often, there was no evidence that they help. For example, the Assign Role pattern, where people start a prompt with “You are a principal JavaScript engineer”, or whatever, generally makes things worse.

Beck and Cunningham predict that their pattern language would eventually contain about 100 to 150 patterns. Had they continued, or at least had they published a complete pattern language in the open, they might have completed their work in private. Then their understanding of designing software and of implementing it in small talk would have moved on. People’s expectations of computers would have moved on. Technology would have moved on. And they would have needed to create new patterns to encapsulate that new knowledge. Part of the problem of the design patterns book, the Gang of Four book, is that it’s a single tome with 23 patterns that was published once and not updated. Contributing to the idea that that’s all you need to know about patterns and pattern languages. In fact, just as built architecture, materials science, and human society moves on, and you need new patterns to encapsulate new problems and solutions in the built environment, the same happens in software, society, and people’s interactions with computers, so we need new design patterns. There are plenty of examples from both commercial software engineering, patterns of enterprise application architecture, security patterns, X-unit test patterns, and more. And academia, the whole plot, that’s Pattern and Language of Programming, series of conferences, of people uncovering and documenting new patterns in software design. They just don’t perhaps get the widespread dissemination and use that they deserve, and that the Gang of Four patterns saw. For those who are interested in finding out about the state of the art in design patterns, check out the Hillside Patterncast, a podcast all about patterns in software.

Beck and Cunningham proposed using the pattern language as the primary design tool for object-oriented software, replacing the, quote, usual rehash of tired old ideas, that is the, quote, force-fit of structured analysis or entity relationship methods. We encountered structured programming a little in the NATO Conference mini-series, particularly in episode 63, but an as-yet-unnumbered future episode on Tom DiMarco’s work will look at the structured analysis and design technique in more detail, which is not really related to structured programming. In both cases, the structured word means structure your approach to, not use a language feature called a structure, a semantic distinction that would have aided adoption of object-oriented techniques, if we’re honest. And here, I’m adding a link to my book, Object-Oriented Programming, the easy way into the show notes purely out of spite.

In structured analysis, at a high level, you think about what you need your software to do in terms of the data it needs to operate on, how those data flow through the system, and decompose the system into modules that operate on the data and pass it to other modules. Yes, you could model those modules as objects, but you haven’t got the full benefit of OOP because you’ve modeled data and behavior separately. In entity relationship modeling, you think about the data schema in terms of the entities reflected in the software design and their attributes and associations. Again, this is a whole system approach and, again, you model the entities as static structures that don’t have the dynamic behavior of objects.

However, we’ve ended up in a world in which many software designers don’t use pattern languages for software design and do favor static software implementations even where they do OOP or post-OOP approaches that are object-oriented in all but name like Swift’s protocol-oriented programming and whatever Rust people call what they do where they make objects that send each other messages.

Where people model their software at all they might use something like UML as in my tool Axminster or the related SysML. Those do include objects and message sending including asynchronous messages so they do model the autonomy of objects but they don’t lend themselves well to modeling introspective object behavior for example where an object receives a selector and decides what method it wants to run and they still end up promoting a whole system approach where you think about what use cases you need to support then invent structure and activity that realizes those use cases. There’s no reason why you couldn’t build up say a sequence diagram by role-playing the objects and deciding how they message each other. It’s just that most people start from the outside and model their whole system then generate code from that model.

So a lot of people who don’t want to use the outside-in approach choose the only known alternative modeling approach that encodes dynamism and learning from experience not modeling at all. Or rather they implicitly model the software in software and then ship the prototype to their customers. That build one to throw away that we talked about in episode 58 becomes build one and sell it and then depend on it forever.

Design patterns ought, as described by Alexander and applied to software by Beck and Cunningham, to fill that space. People do rely on repeatable interaction patterns in software design. Think of the Hashtag, Pull to Refresh, or Hamburger Menu. But they don’t use them in collaboration with the people who use their software except when someone sends a bug report that says I think this list ought to support pull to refresh.

There aren’t that many more opportunities for the people who use software to get involved in designing the software that’s voiced upon them unless they’re lucky enough to work with an XP team. Techniques for getting earlier feedback from customers that many teams use like Lean Startup and the Google Design Sprint still rely on a paternalistic designer-knows-best approach where you build something—even if a lightweight thing like a prototype—and then ask people whether they’d use it. The people who would use it aren’t in charge.

At “scale”, podcaster scare quote fingers deployed, the people who use software are the sources of telemetry data and the subject of experiments that explore those data, not the experiences of the people using the software. So, an A-B test might investigate whether people are more likely to press a particular button, not whether they want to do the thing that that button offers, or whether they’d rather do something else.

I previously gave a talk where I said that one of the reasons people think OOP has failed is that they haven’t tried it. Design patterns is a part of OOP that people went significantly out of their way to miss out on.
Leave a comment